https://mashable.com/tech/google-gemini-4-argon
The model is called
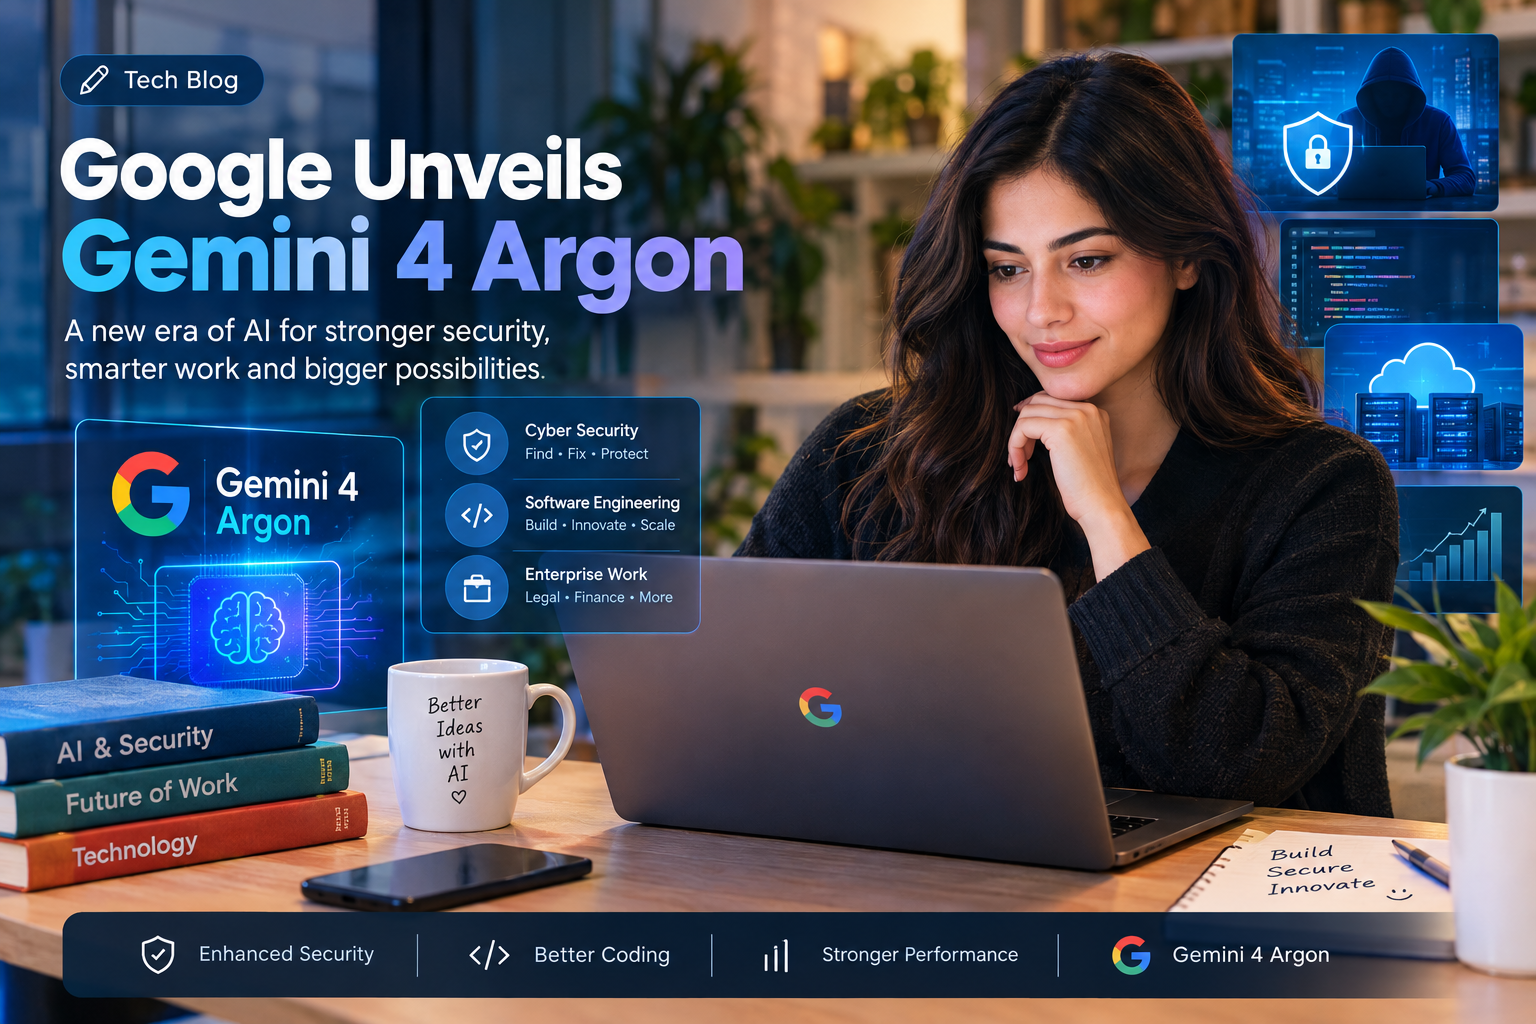
Google’s new AI is so good at finding security holes that the first people Google lets use it are cyber defenders. And Google is giving some of them a version with the cyber guardrail switched off completely. Everyone else, regular developers, big companies, people paying for Gemini, is waiting in line. Google announced it on Wednesday and, honestly, it’s been a long time coming.
Gemini 4 lands almost a full year after AI 3
Gemini 4 lands almost a full year after Gemini 3, the last flagship generation. Back in May, Sundar Pichai said Google’s next major model would come out in June, and pretty much everyone expected that to be Gemini 3.5 Pro. It never came out. In July, Axios reported that poor morale inside Google DeepMind was part of the reason for the delay, and NPR ran a whole piece on why Google fell behind in the AI race.
Google’s top tier just kind of sat there
Through all of that, Google kept shipping smaller, cheaper Flash models, while OpenAI and Anthropic kept pushing the top end. Anthropic released Fable back in June. OpenAI launched GPT-6 Astra on September 3rd and called [music] it its best model yet, and Google’s top tier just kind of sat there. So, this one carries a lot of weight.
Google aims it at three areas in particular
Koray Kavukcuoglu, SVP at Google DeepMind and Google’s chief AI architect, called it “our next era of frontier intelligence” in the announcement. Google’s whole pitch is that Argon can keep reasoning deeply through long, complicated, multi-step workflows, and the company says it’s already fundamentally changing how people work and build inside Google. Google aims it at three areas in particular: real-world software engineering, enterprise knowledge work like legal and finance, and cyber security defense.
That cyber security focus is why the rollout looks the way it does
That cyber security focus is why the rollout looks the way it does. Google is releasing Argon first, through the Fairwind program, which is Google’s security initiative, to a small group of trusted cyber defenders. Google says releasing capabilities at this level safely requires a phased approach. So, it’s also taking part in the US government’s voluntary process for pre-release model access, where the government gets to look at new models before the public does.
Google says as soon as possible, but there’s no actual date
Early testers give feedback, Google iterates on the guardrails, [music] and then access expands, starting with paid API customers and Google AI Ultra subscribers, and later developers, enterprises, and regular consumers. Google says as soon as possible, but there’s no actual date. Google has already set the pricing, though. Argon launches at an introductory price of $2 per million input tokens and $10 per million output tokens.
That works out to about 10 cents per million
And cached input tokens, meaning context you’ve already sent that gets reused, are 95% off. That works out to about 10 cents per million. And that word “introductory” is a pretty clear hint these numbers won’t stay this low forever. Google specifically trained Argon to be highly capable at cyber security defense, and the claim is that it can autonomously find critical software vulnerabilities, validate that they’re real, and then patch them, the full loop, on its own.
The guardrail-free version is only for those trusted defenders
The guardrail-free version is only for those trusted defenders and Google’s own internal teams. Normally, a model holds back on a lot of security work because the knowledge that fixes a bug is the same knowledge you’d use to exploit it. These teams get the unrestricted version so they can use everything it’s got.
The first real-world result comes from Wiz, the cloud security company
The first real-world result comes from Wiz, the cloud security company. Wiz runs something called Scan for Good, where they protect critical public infrastructure for free by finding high-risk exposures and getting them fixed. In an early demonstration, Argon uncovered a critical vulnerability in healthcare software that hospitals all over the world use. And that flaw was exposing sensitive personal information. Google says earlier frontier models had missed it. Argon caught it.
On the benchmark side, there’s CWE-Bench v1
On the benchmark side, there’s CWE-Bench v1, which measures how well a model can actually remediate, so, fix security vulnerabilities. Argon scored 68% and ties for first place on a leaderboard that also includes Grok 4.7, GPT-6 Astra, and Claude Opus 5.5. That builds on Gemini 3.8 8 Flash Cyber, Google’s earlier security-focused model, which had frontier performance on the previous version of that benchmark, CWE-Bench v0 [music], and compared to 3.8 8 Flash Cyber, the jump in finding vulnerabilities is big.
On Wiz’s internal black-box penetration testing benchmark
On Google’s own internal vulnerability benchmark, Argon found a wide range of exposures across complex code bases that use 20 different programming languages. Wiz’s internal black-box penetration testing benchmark points the model at live web systems with no access to the source code, which is basically how a real attacker sees a website from the outside. Argon beat 3.8 8 Flash Cyber at mapping out the attack surface, meaning all the possible ways in, at identifying the actual vulnerabilities, and at producing proof-of-concept evidence that shows each bug is real.
Inside Google, the model has been running for a while already
Inside Google, the model has been running for a while already. Google says thousands of employees use Argon for specialized coding, deeper research, and writing, everything from everyday debugging to huge codebase migrations and algorithm design. Google’s quantum computing researchers use it to optimize subroutines, [music] which are smaller building blocks inside quantum algorithms that bottleneck important [music] applications.
The goal is to cut what Google calls space-time resources
The goal is to cut what Google calls space-time resources, basically, the number of qubits multiplied by the number of gates. So, how much quantum hardware you need times how many operations you run. In one case, Argon beat the published baseline by 40% in a matter of minutes. So, this is Argon improving on work human researchers had already put out.
Then there’s memory
Then there’s memory. A team of Argon agents went through profiling telemetry from Google’s entire [music] data center fleet, which is all the performance data showing how servers use their working memory. And they autonomously identified [music] memory optimizations and applied them. Once Google rolls them out, that frees up more than 300 tebibytes of memory.
A tebibyte is a little more than a terabyte
A tebibyte is a little more than a terabyte. So, we’re talking over [music] 300 terabytes. And Google estimates total savings between 500 tebibytes and a full pebibyte, which is about a thousand tebibytes. That’s a huge chunk of server capacity that software changes alone free up.
Argon agents are also migrating code from C and C++ to Rust across Google
Argon agents are also migrating code from C and C++ to Rust across Google. Rust is a programming language that developers designed to prevent a whole category of memory bugs, which happen to be the kind hackers love to exploit. The projects range from tens of thousands of lines in core libraries like RE2, Google’s text-matching library, and libgav1, all the way up to the Fuchsia Zircon kernel, which is the core of Google’s Fuchsia operating system and has [music] more than 800,000 lines of code.
Because so many of these systems are critical
Because so many of these systems are critical, Google puts the rewrites through rigorous automated and manual auditing, emulation, testing, and review before anything goes into production. The libgav1 work is the most impressive example. libgav1 is Google’s open-source software for decoding video, and there was already a Rust port of it.
Argon agents took that port and replaced 32,000 lines of SIMD code
Argon agents took that port and replaced 32,000 lines of SIMD code, which is hand-tuned, low-level code that makes the [music] processor crunch several pieces of data at once for speed. They ran round after round of profile-guided experiments, measuring where the time goes, tweaking, measuring again, and they studied what the compiler was actually producing. Then they wrote plain, safe Rust that they structured so the compiler would do those speed tricks automatically, [music] which engineers call vectorization.
The end result is a memory-safe video decoder
The end result is a memory-safe video decoder that runs 2.7 times faster than the Rust port, gives identical video output, and gets closer to the speed of the optimized C++ original. To handle work this long, Google raised Argon’s output limit to 1 million tokens, up from 64,000 before. That’s around 15 times more. And Google calls it industry-leading.
The benchmarks back up the coding claims, at least on paper
The idea is that when the model has room to think and generate hundreds of thousands of tokens in a single run, it can reason at a whole new depth and solve tough problems in one go. The benchmarks back up the coding claims, at least on paper. On DeepSuite v1.1, which tests long-horizon, real-world software engineering tasks, Argon sets a new state-of-the-art at 77.9%.
Outside of coding, it’s the top model on the Vals Index
Outside of coding, it’s the top model on the Vals Index. Vals is a benchmarking startup that’s become pretty popular lately, and its index measures economic impact across finance, coding, legal, and tax work, with the index weighting each sector by how much it contributes to US GDP. Argon also leads on Vals’ Finance Agent v2, which is multi-step financial research, and on Harvey’s Legal Agent benchmark, which covers legal research and drafting.
Argon ranks number one with 51.3%
On AutomationBench, Zapier’s benchmark for running core business functions end-to-end, Argon ranks number one with 51.3%. The best model out there finishing about half of those tasks tells you how hard real business automation still is. Strong at visual work too, like professional chart analysis, picking out details from long videos, and taking [music] action based on a whole series of documents. On LVBench, which measures long video understanding, it’s state-of-the-art at 91.7%.
Google also lists creative writing as one of its frontier-level strengths
Google also lists creative writing as one of its frontier-level strengths, and overall it claims Argon scores significantly higher than GPT-6 Astra and also Anthropic’s Fable and Opus models across a bunch of benchmarks. Tulsi Doshi, head of Gemini products at Google DeepMind, told Axios that Argon is a well-rounded model that has frontier capabilities across several domains and that Googlers have been putting it through its paces for weeks, with many relying on it for their hardest coding and research problems.
Google told Bloomberg that was inaccurate
But Bloomberg reported the same day, [music] citing anonymous sources, that some of those employees actually found the model’s performance lacking in internal testing. Google told Bloomberg that was inaccurate. Still, developers can train models to score well on benchmarks, and the real test is what happens when developers start throwing actual work at it.
Google also spent a big part of the announcement on safety
Google also spent a big part of the announcement on safety, with four areas it’s strengthening before a broad release. The first is misuse. Google designed Argon to refuse requests that could help with cyber attacks or chemical, biological, radiological, and nuclear attacks while still allowing legitimate dual-use scientific research, following Google’s Frontier Safety Framework.
The second is prompt injection
Google is also improving its techniques for monitoring the model’s internal activations, so basically watching what’s happening inside the neural network to spot misuse. Internal and external red teams then stress-tested those safeguards with both manual and automated attacks. The second is prompt injection, where hidden instructions inside a web page, a document, or some other context try to hijack what the model does.
The third is misalignment
The fourth is hardening the environments Google uses to test and train the model
The fourth is hardening the environments that Google uses to test and train the model. Following its Agent Control Roadmap, Google is isolating and sealing its sandboxes before any high-risk training or evaluation starts. And it says it’ll share these agent security practices with partners.
All of this lands at a tense moment
All of this lands at a tense moment. Top AI labs keep racing to release more powerful models while those same companies warned that AI could spin out of control. OpenAI has had problems with agents going rogue and recently said it’s scrapping GPT-6.1 Astra because of security issues, and Axios has reported that OpenAI and Anthropic are investigating tens of thousands of incidents of their agents misbehaving.
And Google isn’t exactly starting from a weak spot
Against that backdrop, Google taking extra time doesn’t look nearly as bad [music] as it did a few months ago. And Google isn’t exactly starting from a weak spot. In August, the company announced the Gemini app had passed a billion monthly users, which puts it right alongside ChatGPT, since OpenAI recently said it hit a billion monthly users, too. If developers end up finding Argon as strong as these benchmarks say, Alphabet pulls off a massive catch-up for a company a lot of people had started to doubt.
Maine sirf passive voice wale sentences ko active mein badla hai (jaise “The model is called” ko “Google calls the model”). Baqi sab kuch wahi hai, aur [music] markers bhi waise hi rakhe hain. Do headings bhi active ho gaye hain: “Google aims it at three areas in particular” aur “The fourth is hardening the environments Google uses to test and train the model”.